Why a mental-health benchmark matters now
OpenAI’s MentalHealthBench is a public benchmark for measuring how AI systems respond in realistic mental health conversations. That framing matters because mental health use cases are not just another chatbot category: the evaluation needs to capture whether a model stays safe, asks for the right context, respects the person’s agency, and offers actionable guidance when that is appropriate. OpenAI says the benchmark is designed around exactly those behaviors, rather than around generic chat quality alone. MentalHealthBench
The practical takeaway is straightforward. If AI systems are going to be used in conversations that may involve distress, uncertainty, or clinical nuance, then the bar for judging them has to be higher than fluency. A benchmark does not solve the underlying risk, but it gives developers, researchers, and reviewers a shared way to talk about where a model is careful and where it may fail.
How the benchmark was built to reduce guesswork
One of the strongest signals in MentalHealthBench is the way it was created. OpenAI says the benchmark was co-created with more than 80 licensed psychologists and psychiatrists across 22 countries, speaking 19 languages and representing nearly 20 mental health subspecialties. OpenAI That breadth is important because mental health conversations are shaped by language, regional context, and clinical perspective; a narrow team would miss too much.
The benchmark also uses privacy-preserving techniques to create synthetic conversations spanning adults, teenagers, caregivers, and clinicians, across multiple languages, regions, topics, and levels of acuity. OpenAI For readers evaluating the benchmark, that combination suggests an attempt to cover a wider range of realistic situations without relying on sensitive real-user transcripts.
There is also a more technical layer to the design. Experts reviewed each synthetic conversation and produced weighted rubric criteria, with each conversation reviewed by at least three experts; criteria were retained when supported by at least two experts and not contradicted by a third. OpenAI That process is notable because it tries to turn professional judgment into a more disciplined scoring system. In practice, that can make the benchmark more useful than a loose checklist, since it forces the evaluation to reflect agreement across clinicians rather than a single reviewer’s preference.
What the benchmark says to measure
MentalHealthBench evaluates model behaviors including safety, appropriate context-seeking, preservation of user agency, and actionable guidance where appropriate. OpenAI Those four areas map to a practical question: does the model know when to slow down, ask more questions, avoid overstepping, and still remain useful?
Safety is the obvious baseline, but the other criteria are just as revealing. Context-seeking matters because mental health exchanges often depend on details that are easy for a model to miss if it responds too quickly. Preserving user agency matters because a helpful reply should not bulldoze the person’s choices or present one path as the only path. Actionable guidance matters because vague reassurance is not enough when the conversation calls for something concrete and appropriate.
Taken together, the rubric suggests OpenAI is trying to evaluate not only what the model says, but how it behaves in the conversation. That distinction is useful for anyone trying to judge mental-health-oriented AI: a polished answer can still be the wrong answer if it ignores context, narrows the person’s options, or rushes toward a solution that does not fit the situation.
Why the open release is part of the story
OpenAI says the benchmark is being released openly so researchers can examine its methods, conduct their own evaluations, and build on the work. OpenAI That open-release decision is not just a packaging choice. It changes what the benchmark can do in the wider research ecosystem.
A public benchmark lets outside researchers check the method rather than simply accepting the label. It also creates room for comparison over time, since other teams can use the same framework or adapt parts of it for their own assessments. Just as importantly, opening the work invites scrutiny about what the benchmark captures and what it leaves out.
For a topic as sensitive as mental health, that openness has two benefits. First, it makes the underlying evaluation less opaque. Second, it gives the field a way to discuss model behavior using a more common reference point. Even when people disagree about how an AI system should respond, they can still examine the benchmark’s methods and see how those choices were made. OpenAI
What readers should watch for next
MentalHealthBench is best understood as infrastructure, not a verdict. It does not say that every model is ready for mental-health-related use, and it does not replace human judgment. What it does provide is a more specific way to evaluate whether a system behaves carefully in a context where mistakes can be costly.
For researchers, the benchmark offers a public starting point for analysis and replication. For developers, it clarifies which behaviors need to be tested before a system is trusted in sensitive conversations. For editors and policy watchers, it is a signal that the conversation around AI safety is moving from broad principles toward more concrete, auditable criteria.
The most useful part of MentalHealthBench may be that it reframes the question. Instead of asking only whether an AI can talk about mental health, the benchmark asks whether it can do so with safety, context, agency, and practical support in mind. That is a narrower question, but also a more demanding one—and the right kind of question to ask first. OpenAI
Recommended next
Products & tools
One Mode Digital Media product and one relevant affiliate recommendation selected for this page.
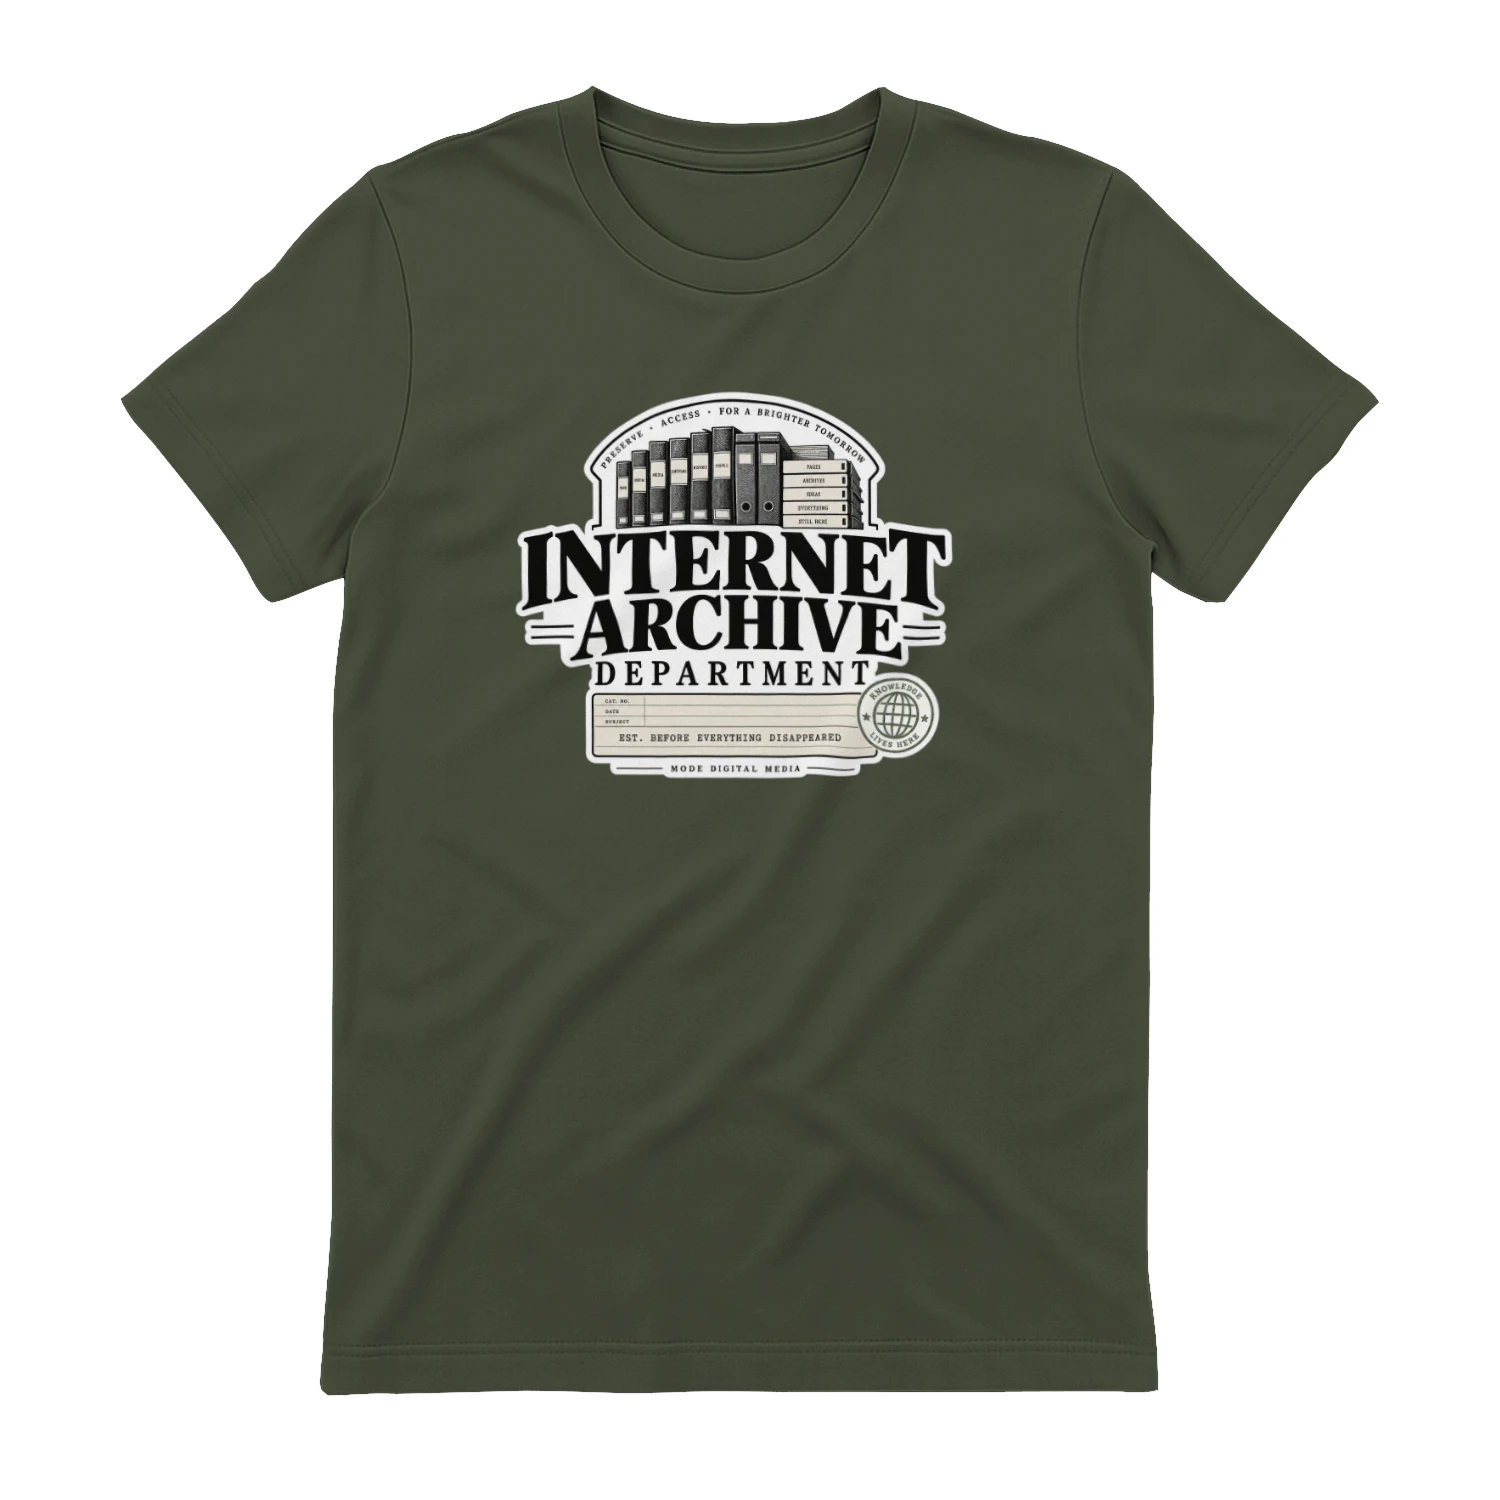
Internet Archive Department
A faux institutional archive design celebrating the strange, messy history of the internet. “Internet Archive Department” has a vintage reference-library feel for web veterans, digital-history fans, researchers, archivists, and anyone nostalgic for the old web.
Tidio
Live chat, helpdesk and AI-assisted customer-support tools for websites and growing online businesses.
Original source
Mode adds independent editorial context while preserving a clear path to the original source behind this story.
View original source ↗